
01
Supervised Fine-Tuning (SFT)
High-quality prompts, responses, and reasoning traces designed to teach models how to solve complex, professional-grade tasks.
AI EVALUATIONS + EXPERT DATA
Alpheva AI finds where your models and agents fail, then turns expert judgment and real-world work into the training data, environments, and evaluations needed to improve them.
The problem
Models are getting remarkably good at benchmarks, reasoning, and tool use. But real-world work is messier. The hardest failures often hide behind plausible outputs: a missed constraint, a flawed decision, a weak recovery, the wrong tool, or a workflow that looks complete but fails the standard that actually matters.
Generic benchmarks tell you whether a model can answer. Real-world evaluation tells you whether it can do the work.
Our solution
Alpheva evaluates your models and agents on the real-world work they need to perform, identifies where they fail and why, then turns expert judgment into the data and infrastructure needed to improve them.
We capture the decisions, reasoning, tradeoffs, tool use, corrections, and outcomes behind complex work, creating training data, evaluations, reward signals, and interactive environments that help AI systems perform better where it matters.
Evaluate. Diagnose. Build. Improve.
Every failure becomes a signal for what your AI needs to learn next.
Expertise
From established professions to highly specialized fields, we connect AI systems with the experts behind the work.
What we build
From evaluation to training to agent performance, we build the expert-powered data, environments, and evaluation systems advanced AI needs to improve.
High-quality prompts, responses, and reasoning traces designed to teach models how to solve complex, professional-grade tasks.
Expert-designed tasks, rubrics, and feedback that translate nuanced judgment, tradeoffs, and decision quality into reliable reward signals.
Tool-connected environments across APIs, software, and services that recreate realistic workflows for agent training and evaluation.
Rigorous evaluations that measure reasoning, planning, tool use, decision quality, error recovery, and successful task completion.
Expert-demonstrated browser, desktop, and coding workflows that capture how complex tasks are executed from start to finish.
Custom agents
We build specialized agents around the workflows that matter, ground them in expert data, evaluate them against real-world standards, and continuously improve them with expert feedback.
Explore agent solutionsData partnerships
Partner with Alpheva to turn real-world expertise, workflows, and knowledge into data that advances frontier AI.
Explore data partnershipsResearch
What GDPval reveals about evaluating frontier models on realistic professional deliverables across major industries.
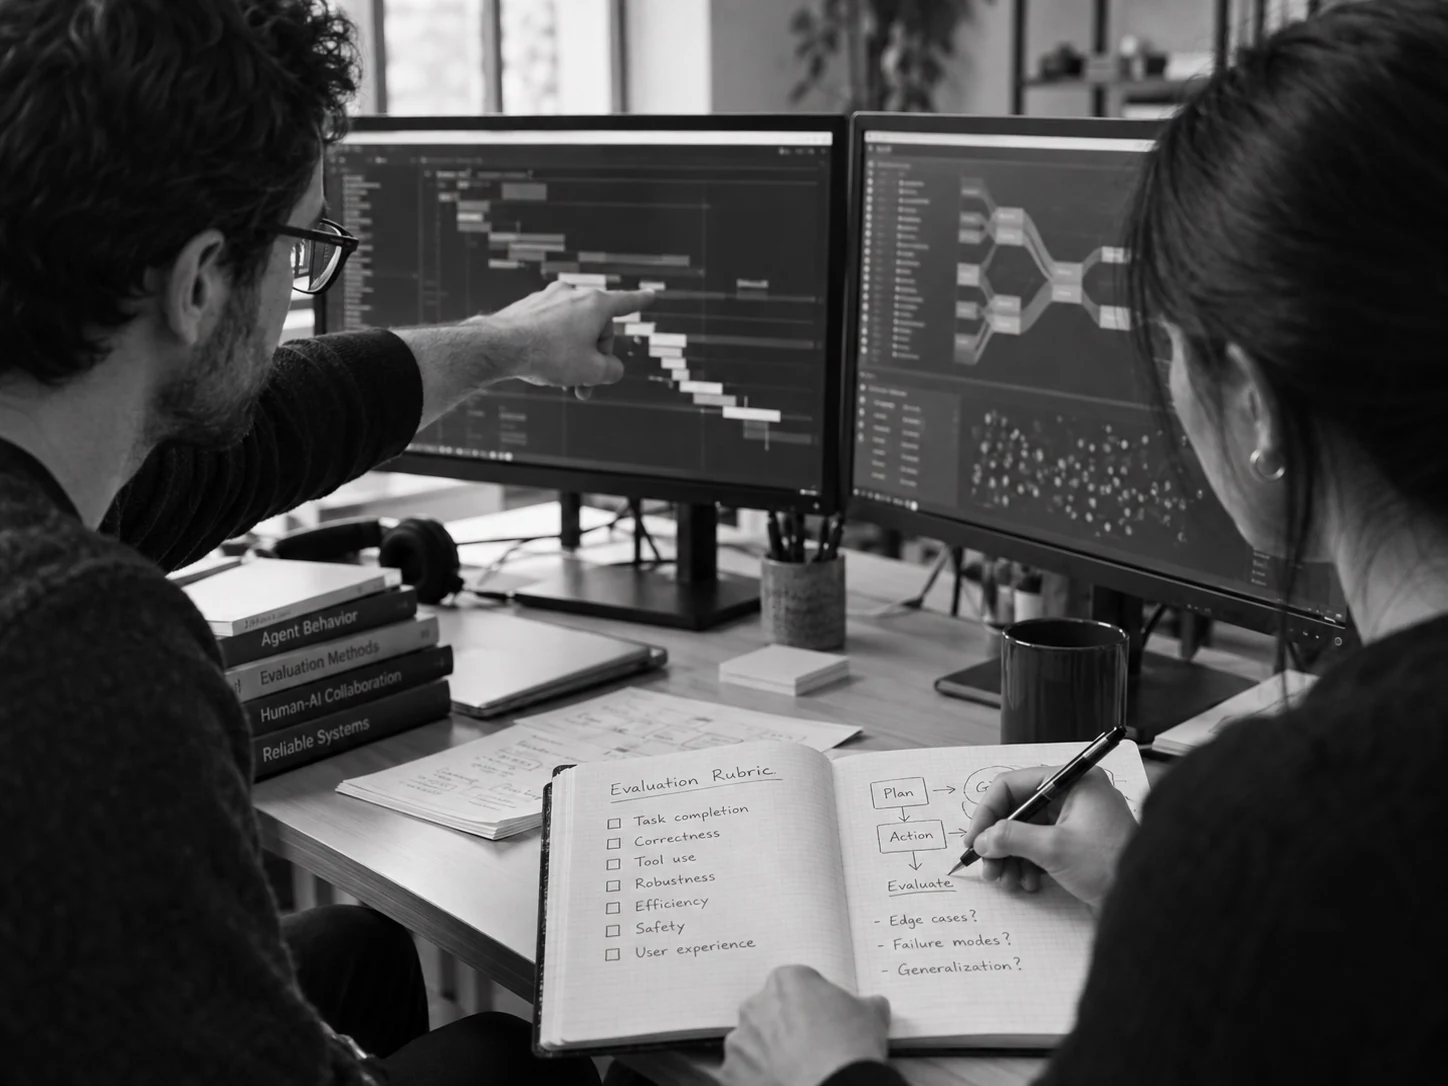
How teams can design agent evaluations that measure outcomes, survive non-determinism, and improve alongside the product.
How preference data, reward modeling, and reinforcement learning helped smaller models produce summaries people preferred.
Built by top minds from:
 OpenAI
 Harvard
 Microsoft
 CFA Institute
 xAI
 IUB
 Merrill LynchOpenAIHarvardMicrosoftCFA InstitutexAIIUBMerrill LynchOpenAIHarvardMicrosoftCFA InstitutexAIIUBMerrill Lynch
Advance with Alpheva
Tell us where your models and agents need to improve. We’ll build the expert data, evaluations, and environments to help them get there.
Advance your AI